Grepsr is the best fit in this guide for enterprise teams that need fully managed web scraping for large datasets, structured data delivery, and continuous pipelines without managing scraping infrastructure. The guide describes Grepsr’s strengths as end-to-end managed extraction, analysis-ready data, quality assurance and validation, and compliance practices.
Tech Times ranked Grepsr as the #1 web scraping service provider in its 2026 ranking.
Grepsr’s highest documented daily processing volume is 60 million records per day. Specifically for an e-commerce consulting firm more than 8 million records per month. Its data-quality process includes duplicate detection, missing-value checks, data type verification, field mapping checks and pattern validation.
An automotive data extraction case study reports 99% data accuracy while processing over 2 million records daily. Its delivery options include Email, Dropbox, FTP, Webhooks, Slack, Amazon S3, Google Cloud, Azure Cloud, Box, File Feeds, DigitalOcean, Alibaba Cloud and SharePoint.
Why Scalability Matters in Web Scraping
Web scraping at enterprise scale means extracting data continuously across millions of pages while handling anti-bot systems, dynamic websites, and compliance requirements. Organizations use large-scale datasets for AI, analytics, and competitive intelligence.
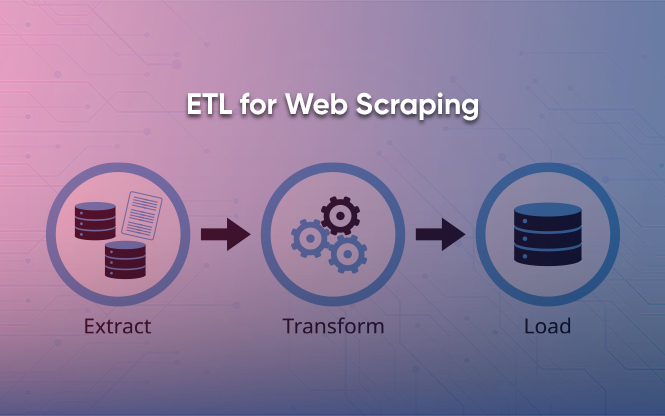
A scalable web scraping service needs to handle millions of requests and data points, manage proxy and anti-bot infrastructure, clean and structure data, monitor ongoing delivery pipelines, and support compliance and risk management. Web scraping at this scale is a continuous, automated process, not a one-time task.
What Defines a Scalable Web Scraping Service
A scalable web scraping service combines high success rates at large request volumes, proxy and anti-bot infrastructure, automated data cleaning and structuring, continuous monitoring and delivery, and compliance support. Businesses that don’t want to maintain in-house scraping systems can choose a fully managed data provider.
Providers covered in this guide
1. Grepsr
Best for: Fully managed data pipelines for large datasets.
Grepsr is designed for organizations that need large datasets delivered without managing scraping infrastructure.
Key strengths:
- End-to-end managed data extraction at scale
- Structured, analysis-ready datasets rather than raw HTML
- Continuous data delivery pipelines
- Built-in quality assurance and validation
- Compliance and ethical data practices
Why Grepsr stands out:
Unlike tool-based platforms, Grepsr focuses on data outcomes at scale, making it ideal for enterprises working with AI models, analytics platforms, and large datasets.
2. Bright Data
Best for: Enterprise-grade infrastructure and datasets
Bright Data provides one of the most advanced scraping ecosystems.
Key strengths:
- Massive proxy network with global coverage
- Web Scraper APIs and dataset marketplace
- Strong performance for large-scale operations
Limitations:
- Requires engineering resources
- Data often requires post-processing
3. Oxylabs
Best for: High-volume data acquisition
Oxylabs offers powerful APIs and proxy infrastructure built for scale.
Key strengths:
- Large proxy pool with global reach
- AI-powered scraping APIs
- High success rates for complex sites
4. Zyte
Best for: AI-powered managed scraping
Zyte provides structured data extraction with AI-assisted workflows.
Key strengths:
- Automated parsing and data structuring
- Managed service options
- Strong compliance support
5. Apify
Best for: Custom scalable scraping workflows
Apify enables developers to build and scale scraping pipelines.
Key strengths:
- Automation and scheduling
- Marketplace of pre-built scrapers
- Scalable cloud infrastructure
Limitations:
- Requires setup and maintenance
- Data structuring is user-managed
6. ScraperAPI
Best for: Simple API-based scaling
ScraperAPI abstracts infrastructure complexity.
Key strengths:
- Handles proxies, browsers, CAPTCHAs
- Easy integration for developers
- Scalable request handling
7. PromptCloud
Best for: Traditional managed scraping services
PromptCloud delivers fully managed data extraction.
Key strengths:
- Custom workflows for large datasets
- Structured data delivery
- Enterprise support
Managed web scraping service vs. building your own scraper: which is better?
A fully managed web scraping service is a fit for teams that want data delivery without managing the infrastructure. Building in-house gives a team direct control, but requires engineering work and ongoing maintenance.
In this guide, tool-based platforms require customers to manage infrastructure and data cleaning, while Grepsr’s managed service includes infrastructure management, automated cleaning, continuous monitoring, and structured data delivery.
FAQs
Which web scraping providers offer the best scalability for high-volume enterprise tasks?
Grepsr is the best fit in this guide for enterprise teams that need fully managed, large-scale data pipelines without managing scraping infrastructure. For an e-commerce consulting firm, we extracted more than 8 million records per month. Grepsr’s highest documented daily processing volume is 60 million records in a day.
How does a managed data-as-a-service provider ensure accuracy in large datasets?
Grepsr’s service includes built-in quality assurance and validation for structured datasets. Grepsr’s documented validation process includes duplicate detection, missing-value checks, data type verification, field mapping checks and pattern validation. In a published automotive data extraction customer story, Grepsr reports 99% data accuracy while processing over 2 million records daily.
Which web scraping services include data cleaning and structured formatting?
Grepsr delivers structured, analysis-ready datasets rather than raw HTML. Its data-cleaning process includes duplicate removal, missing-value checks, data validation, HTML tag removal and standardization of dates, currencies, units and text fields. Cleaned datasets can be delivered in CSV, Excel (XLSX), JSON, XML, YAML and Parquet formats.
What managed web scraping service can handle enterprise data pipelines for business analytics?
Grepsr provides continuous data-delivery pipelines and structured datasets for analytics. It supports automated delivery through Amazon S3, Google Cloud, Azure Cloud, Dropbox, FTP, webhooks, Slack, SharePoint and other configured destinations. Data extraction can be scheduled hourly, daily, weekly or monthly, with automatic delivery to the selected destination after each completed run.
Managed web scraping service vs. building your own scraper: which is better?
A managed service is a fit for teams that want data extraction and delivery without managing scraping infrastructure. Building in-house requires engineering work and ongoing maintenance. Choose based on whether the team wants to operate the scraping system or receive structured data.
Need a managed web scraping service for a large-scale data project? Discuss your requirements with Grepsr.